
计算溶液所需的质量、体积或浓度。
为什么选择此级别
,适用于对基线干扰要求严格的色谱和分析工作流程。
储存与运输
-20°C储存,避免反复冻融。超低温运输 。请查阅批次 COA 获取详细规格。
质量文档
SDS、COA、产品数据表及规格说明书均可下载。可通过批号查询获取批次 COA。
文献证明
在色谱分析、有机合成和交叉偶联反应领域已被 0 篇同行评审文献引用。
概述
|
产品简介
NGS Combinatorial Dual Index Primers Kit for Illumina (Set I)是 Illumina 高通量测
序平台文库构建专用index接头引物试剂盒。本试剂盒包含通用接头DNA Adaptor for
Illumina、8 种 i5 Index Primers 以及 12 种 i7 Index Primers,配合Fast DNA Library
Prep Set for Illumina & MGI和NGS Frag Fast DNA Library Prep Set for
Illumina使用,可用于构建多至 96 种不同组合的双端Index标记二代测序
文库。制备的文库可用于NovaSeq,MiSeq,HiSeq 2000/2500/3000/4000,MiniSeq
和NextSeq等测序平台的测序。试剂盒中提供的所有试剂都经过严格的质量控制和功
能验证,最大程度上保证了文库构建的稳定性和重复性。
适用范围
适用于Illumina高通量测序平台双端 Index标记文库构建。推荐与Fast DNA Library Prep Set for Illumina & MGI和NGS Frag Fast DNA Library Prep Set for Illumina配合使用。
产品组分
|
注:单个文库DNA Adapter for Illumina的使用量依据起始模板投入量而定, i7 Index Primers 和i5 Index
Primers使用量均为2.5 μl。
序列信息
DNA Adapter for Illumina
5´-/Phos/ GATCGGAAGAGCACACGTCTGAACTCCAGT*C -3´
5´-ACACTCTTTCCCTACACGACGCTCTTCCGATC*T-3´
(*表示硫代, Phos表示磷酸化)
i5 Index Primers
5´-AATGATACGGCGACCACCGAGATCTACAC
[i5]ACACTCTTTCCCTACACGACGCTCTTCCGATC*T-3´
i7 Index Primers
5´-CAAGCAGAAGACGGCATACGAGAT
[i7]GTGACTGGAGTTCAGACGTGTGCTCTTCCGATC*T-3´
*表示硫代)
[i5]表示8 bp i5 Index序列,[i7]表示8 bp i7 Index序列。
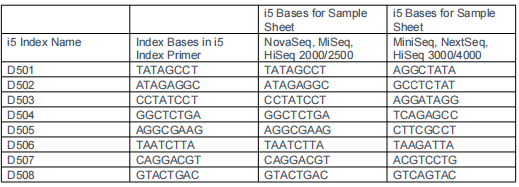
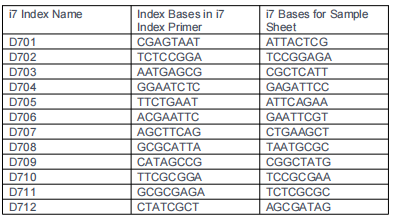
各引物对应的Index名称、引物中包含的Index序列以及测序时Sample Sheet中输入的 Index序列信息如下表所示:
|
建库流程和文库结构
本试剂盒与Fast DNA Library Prep Set for Illumina & MGI和NGS Frag Fast DNA Library Prep Set for Illumina配合使用,文库构建流程示 意图如下:

构建好的文库结构如下
5’- AATGATACGGCGACCACCGAGATCTACAC [i5]
ACACTCTTTCCCTACACGACGCTCTTCCGATCT [DNA insert]
AGATCGGAAGAGCACACGTCTGAACTCCAGTCAC [i7]
ATCTCGTATGCCGTCTTCTGCTTG-3’
i5:i5 index, 8 bases
i7:i7 index, 8 bases
DNA insert:插入的目标测序序列
|
Products Introduction
The NGS Combinatorial Dual Index Primers Kit for Illumina (Set I) is an index primer kit for library construction on the Illumina high-throughput sequencing platform. This kit contains the Universal Junction DNA Adaptor for Illumina, 8 i5 Index Primers, and 12 i7 Index Primers for use with the Fast DNA Library Prep Set for Illumina & MGI and the NGS Frag Fast DNA Library Prep Set for Illumina. Library Prep Set for Illumina, 8 i5 Index Primers, and 12 i7 Index Primers can be used with the Fast DNA Library Prep Set for Illumina & MGI and the NGS Frag Fast DNA Library Prep Set for Illumina to build up to 96 different combinations of bipartite Index-tagged second generation sequencing libraries. The prepared libraries can be used for sequencing on NovaSeq, MiSeq, HiSeq 2000/2500/3000/4000, MiniSeq and NextSeq sequencing platforms. All the reagents provided in the kit have been subjected to stringent quality control and functional validation to maximize the stability and reproducibility of the library construction.
Scope of application
For use with Illumina High-Throughput Sequencing Platform Double-Ended Index Labeled Library Construction. Recommended for use with Fast DNA Library Prep Set for Illumina & MGI and NGS Frag Fast DNA Library Prep Set for Illumina.
product components
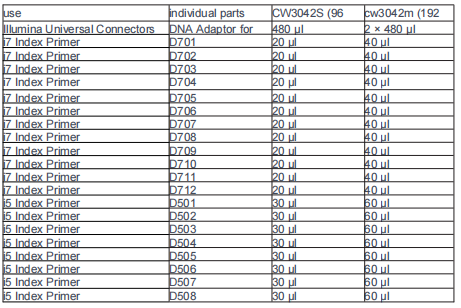
Note: The amount of individual library DNA Adapter for Illumina used depends on the amount of starting template input. i7 Index Primers and i5 Index Primers both use 2.5 μl.
Sequence information
DNA Adapter for Illumina
5´-/Phos/ GATCGGAAGAGCACACGTCTGAACTCCAGT*C -3´
5´-ACACTCTTTCCCTACACGACGCTCTCTTCCGATC*T-3´
(* denotes thiolation, Phos denotes phosphorylation)
i5 Index Primers 5´-AATGATACGGCGACCACCGAGATCTACAC [i5]ACACTCTTTCCCTACACGACGCTCTTCCGATC*T-3´
i7 Index Primers
5´-CAAGCAGAAGACGGCATACGAGAT
[i7]GTGACTGGAGTTCAGACGTGTGCTCTTCCGATC*T-3´.
* denotes thio)
[i5] denotes an 8 bp i5 Index sequence and [i7] denotes an 8 bp i7 Index sequence.
The Index name corresponding to each primer, the Index sequence contained in the primer, and the Index entered in the Sample Sheet during sequencing.
Library building process and library structure
This kit is used in conjunction with Fast DNA Library Prep Set for Illumina & MGI and NGS Frag Fast DNA Library Prep Set for Illumina, and the library construction process is summarized below:
The structure of the constructed library is as follows
5'- AATGATACGGCGACCACCGAGATCTACAC [i5] ACACTCTTTCCCTACACGACGCTCTTCCGATCT [DNA insert] AGATCGGAAGAGCACACGTCTGAACTCCAGTCAC [i7] ATCTCGTATGCCGTCTTCTGCTTG-3' i5: i5 index, 8 bases i7: i7 index, 8 bases DNA insert: inserted target sequencing sequence

规格
别名
Illumina 的 NGS 组合双索引引物试剂盒(套件 I)
英文名称
NGS Combinatorial Dual Index Primers Kit for Illumina (Set I)
储存条件
-20°C储存,避免反复冻融
运输条件
超低温运输
产品线
生物产品
名称和识别符
分子类型
试剂盒
技术文档
高级数据
质检证书(CoA,COO,BSE/TSE 和分析图谱)
C of A & Other Certificates(BSE/TSE, COO):
输入批号以搜索分析图谱:
技术文档和文章
溶液计算器
产品仅提供给经过验证的企业、机构和合格的专业人员用于研发。不适用于人类、动物、诊断或治疗。
Copyright © 2023至今 上海阿拉丁生化科技股份有限公司 保留所有权利。


 危险品化学品经营许可证(带存储)